Tag Archives | linux

Sailfish OS yeni bir on yıla hazırlanıyor

Hatırlanacağı gibi, yaklaşık 10 yıl önce, Nokia’nın işten çıkardığı mühendisler tarafından kurulan Jolla adlı şirketin ilk akıllı telefonu Jolla, Finlandiya’dan Hong Kong’a kadar 136 ülkede satışa sunulmuştu. Eski Nokia çalışanlarının kurduğu şirket, telefon üzerinde Sailfish OS adlı bir işletim sistemi kullanıyordu. 10 yıllık bir sürecin ardından, Sailfish OS için yeni bir 10 yıllık süreç için hazırlıklar sürdürülüyor. Geliştirici ekibin, blog.jolla’da paylaştığı yazıyla, gündemdeki bazı ayrıntılar dile getirildi. Buna göre; Buna ek olarak, ürün yol haritasının Sailfish OS geliştiricileri için çeşitli önemli güncellemeler içerdiği belirtiliyor: Derleyici araç zincirinin güncellenmesi, SDK geliştirme çalışmaları ve geliştiricilere yerel Sailfish OS uygulamaları oluşturmada daha iyi hizmet verilmesi için belgelerle daha fazla API sunulması tasarıları bunlardan bazıları. Bu arada, kimi çevreler, blogda çok fazla ayrıntının paylaşılmadığını düşünüyor ve duruma eleştirel bir tavır koyuyor.

Continue Reading →

Geliştirici ekip; 2019 boyunca, çeşitli kullanıcı deneyimi iyileştirmeleri, uygulama yönetimi ve yeniden tasarımı için geliştirmeler ve önemli özellikler ile artık uyumlu Sailfish cihazları için Android 8.1 düzeyindeki uygulamalar için destek de dahil olmak üzere, benzersiz Linux uygulamalarındaki Android uygulamalarının bir başka sürümünü yayınladıklarını söylüyor. Jolla yeni lisanslama politikasıyla müşterileri çekmek için çalışırken, Sailfish X topluluk programları yoluna devam ediyor. Kullanıcı arabirimi için güvenlik mimarisinin iyileştirilmesi, gizliliği koruyan çok kullanıcılı destek ve bulut tabanlı hizmetler için yeni etkinleştiricilerin gündeme alınması ilk ifade edilen ayrıntılar. Yeni ülkelerde, yeni lisanslama ortaklıkları üzerinde çalıştıklarını belirten geliştirici ekip, bu işlerin üstesinden gelmenin çok zaman aldığını ve 2020’nin ilk yarısında bunları çözmek ve yaşamak için çok çalışacaklarını söylüyor. Konu hakkında ayrıntılı bilgiyi blog.jolla.com’da Sami Pienimäki’nin yayımladığı yazıda bulabilirsiniz.

0

Linux find command tutorial (with examples)

When it comes to locating files or directories on your system, the find command on Linux is unparalleled. It’s simple to use, yet has a lot of different options that allow you to fine-tune your search for files. Read on to see examples of how you can wield this command to find anything on your system. Every file is only a few keystrokes away once you know how to use the find command in Linux. You can tell the find command to look specifically for directories with the -type d option. This will make find command only search for matching directory names and not file names. Since hidden files and directories in Linux begin with a period, we can specify this search pattern in our search string in order to recursively list hidden files and directories.

Continue Reading →

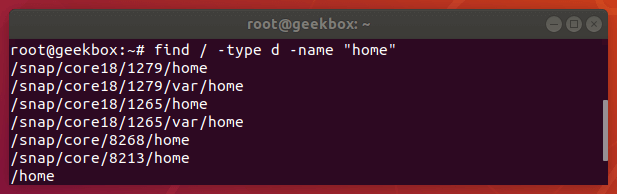
Find a directory

You can tell the find command to look specifically for directories with the -type d option. This will make find command only search for matching directory names and not file names.

find /path/to/search -type d -name "name-of-dir"

Find directory

Find hidden files

Since hidden files and directories in Linux begin with a period, we can specify this search pattern in our search string in order to recursively list hidden files and directories.

find /path/to/search -name ".*"

Find files of a certain size or greater than X

The -size option on find allows us to search for files of a specific size. It can be used to find files of an exact size, files that are larger or smaller than a certain size, or files that fit into a specified size range. Here are some examples:

Search for files bigger than 10MB in size:

find /path/to/search -size +10M

Search for files smaller than 10MB in size:

find /path/to/search -size -10M

Search for files that are exactly 10MB in size:

find /path/to/search -size 10M

Search for files that are between 100MB and 1GB in size:

find /path/to/search -size +100M -size -1G

Find from a list of files

If you have a list of files (in a .txt file, for example) that you need to search for, you can search for your list of files with a combination of the find and grep commands. For this command to work, just make sure that each pattern you want to search for is separated by a new line.

find /path/to/search | grep -f filelist.txt

The -f option on grep means “file” and allows us to specify a file of strings to be matched with. This results in the find command returning any file or directory names that match those in the list.

Find not in a list

Using that same list of files we mentioned in the previous example, you can also use find to search for any files that do not fit the patterns inside the text file. Once again, we’ll use a combination of the find and grep command; we just need an additional option specified with grep:

find /path/to/search | grep -vf filelist.txt

The -v option on grep means “inverse match” and will return a list of files that don’t match any of the patterns specified in our list of files.

Set the maxdepth

The find command will search recursively by default. This means that it will search the specified directory for the pattern you specified, as well as any and all subdirectories within the directory you told it to search.

For example, if you tell find to search the root directory of Linux (/), it will search the entire hard drive, no matter how many subdirectories of subdirectories exist. You can circumvent this behavior with the -maxdepth option.

Specify a number after -maxdepth to instruct find on how many subdirectories it should recursively search.

Search for files only in the current directory and don’t search recursively:

find . -maxdepth 0 -name "myfile.txt"

Search for files only in the current directory and one subdirectory deeper:

find . -maxdepth 1 -name "myfile.txt"

Find empty files (zero-length)

To search for empty files with find, you can use the -empty flag. Search for all empty files:

find /path/to/search -type f -empty

Search for all empty directories:

find /path/to/search -type d -empty

It is also very handy to couple this command with the -delete option if you’d like to automatically delete the empty files or directories that are returned by find.

Delete all empty files in a directory (and subdirectories):

find /path/to/search -type f -empty -delete

Find largest directory or file

If you would like to quickly determine what files or directories on your system are taking up the most room, you can use find to search recursively and output a sorted list of files and/or directories by their size.

How to show the biggest file in a directory:

find /path/to/search -type f -printf "%s\t%p\n" | sort -n | tail -1

Notice that the find command was sorted to two other handy Linux utilities: sort and tail. Sort will put the list of files in order by their size, and tail will output only the last file in the list, which is also the largest.

You can adjust the tail command if you’d like to output, for example, the top 5 largest files:

find /path/to/search -type f -printf "%s\t%p\n" | sort -n | tail -5

Alternatively, you could use the head command to determine the smallest file(s):

find /path/to/search -type f -printf "%s\t%p\n" | sort -n | head -5

If you’d like to search for directories instead of files, just specify “d” in the type option. How to show the biggest directory:

find /path/to/search -type d -printf "%s\t%p\n" | sort -n | tail -1

Find setuid set files

Setuid is an abbreviation for “set user ID on execution” which is a file permission that allows a normal user to run a program with escalated privileges (such as root).

This can be a security concern for obvious reasons, but these files can be easy to isolate with the find command and a few options.

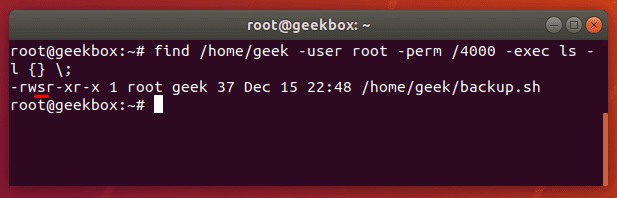
The find command has two options to help us search for files with certain permissions: -user and -perm. To find files that are able to be executed with root privileges by a normal user, you can use this command:

find /path/to/search -user root -perm /4000

Find suid files

In the screenshot above, we included the -exec option in order to show a little more output about the files that find returns with. The whole command looks like this:

find /path/to/search -user root -perm /4000 -exec ls -l {} \;

You could also substitute “root” in this command for any other user that you want to search for as the owner. Or, you could search for all files with SUID permissions and not specify a user at all:

find /path/to/search -perm /4000

Find sgid set files

Finding files with SGID set is almost the same as finding files with SUID, except the permissions for 4000 need to be changed to 2000:

find /path/to/search -perm /2000

You can also search for files that have both SUID and SGID set by specifying 6000 in the perms option:

find /path/to/search -perm /6000

List files without permission denied

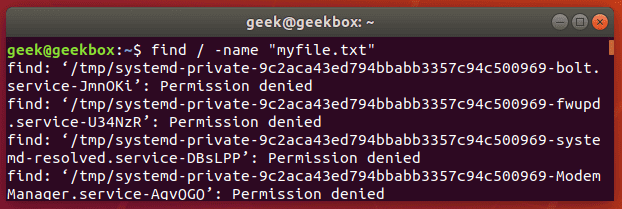
When searching for files with the find command, you must have read permissions on the directories and subdirectories that you’re searching through. If you don’t, find will output an error message but continue to look throughout the directories that you do have permission on.

Permission denied

Although this could happen in a lot of different directories, it will definitely happen when searching your root directory.

That means that when you’re trying to search your whole hard drive for a file, the find command is going to produce a ton of error messages.

To avoid seeing these errors, you can redirect the stderr output of find to stdout, and pipe that to grep.

find / -name "myfile.txt" 2>%1 | grep -v "Permission denied"

This command uses the -v (inverse) option of grep to show all output except for the lines that say “Permission denied.”

Find modified files within the last X days

Use the -mtime option on the find command to search for files or directories that were modified within the last X days. It can also be used to search for files older than X days, or files that were modified exactly X days ago.

Here are some examples of how to use the -mtime option on the find command:

Search for all files that were modified within the last 30 days:

find /path/to/search -type f -mtime -30

Search for all files that were modified more than 30 days ago:

find /path/to/search -type f -mtime +30

Search for all files that were modified exactly 30 days ago:

find /path/to/search -type f -mtime 30

If you want the find command to output more information about the files it finds, such as the modified date, you can use the -exec option and include an ls command:

find /path/to/search -type f -mtime -30 -exec ls -l {} \;

Sort by time

To sort through the results of find by modified time of the files, you can use the -printf option to list the times in a sortable way, and pipe that output to the sort utility.

find /path/to/search -printf "%T+\t%p\n" | sort

This command will sort the files older to newer. If you’d like the newer files to appear first, just pass the -r (reverse) option to sort.

find /path/to/search -printf "%T+\t%p\n" | sort -r

Difference between locate and find

The locate command on Linux is another good way to search for files on your system. It’s not packed with a plethora of search options like the find command is, so it’s a bit less flexible, but it still comes in handy.

locate myfile.txt

The locate command works by searching a database that contains all the names of the files on the system. The database that it searches through is updated with the upatedb command.

Since the locate command doesn’t have to perform a live search of all the files on the system, it’s much more efficient than the find command. But in addition to the lack of options, there’s another drawback: the database of files only updates once per day.

You can update this database of files manually by running the updatedb command:

updatedb

The locate command is particularly useful when you need to search the entire hard drive for a file, since the find command will naturally take a lot longer, as it has to traverse every single directory in real-time.

If searching a specific directory, known to not contain a large number of subdirectories, it’s better to stick with the find command.

CPU load of find command

When searching through loads of directories, the find command can be resource-intensive. It should inherently allow more important system processes to have priority, but if you need to ensure that the find command takes up fewer resources on a production server, you can use the ionice or nice command.

Monitor CPU usage of the find command:

top

Reduce the Input/Output priority of find command:

ionice -c3 -n7 find /path/to/search -name "myfile.txt"

Reduce the CPU priority of find command:

nice -n 19 find /path/to/search -name "myfile.txt"

Or combine both utilities to really ensure low I/O and low CPU priority:

nice -n ionice -c2 -n7 find /path/to/search -name "myfile.txt"

I hope you find the tutorial useful. Keep coming back.

0

SSH port forwarding (tunneling) in Linux

In this tutorial, we will cover SSH port forwarding in Linux. This is a function of the SSH utility that Linux administrators use to create encrypted and secure relays across different systems. SSH port forwarding, also called SSH tunneling, is used to create a secure connection between two or more systems. Applications can then use these tunnels to transmit data. Your data is only as secure as its encryption, which is why SSH port forwarding is a popular mechanism to use. Read on to find out more and see how to setup SSH port forwarding on your own systems. To put it simply, SSH port forwarding involves establishing an SSH tunnel between two or more systems and then configuring the systems to transmit a specified type of traffic through that connection.

Continue Reading →

What is SSH port forwarding?

To put it simply, SSH port forwarding involves establishing an SSH tunnel between two or more systems and then configuring the systems to transmit a specified type of traffic through that connection.

There are a few different things you can do with this: local forwarding, remote forwarding, and dynamic port forwarding. Each configuration requires its own steps to setup, so we will go over each of them later in the tutorial.

Local port forwarding is used to make an external resource available on the local network. An SSH tunnel is established to a remote system, and traffic from the local network can use that tunnel to transmit data back and forth, accessing the remote system and network as if it was a part of the local network.

Remote port forwarding is the exact opposite. An SSH tunnel is established but the remote system is able to access your local network.

Dynamic port forwarding sets up a SOCKS proxy server. You can configure applications to connect to the proxy and transmit all data through it. The most common use for this is for private web browsing or to make your connection seemingly originate from a different country or location.

SSH port forwarding can also be used to setup a virtual private network (VPN). You’ll need an extra program for this called sshuttle. We cover the details later in the tutorial.

Why use SSH port forwarding?

Since SSH creates encrypted connections, this is an ideal solution if you have applications that transmit data in plaintext or use an unencrypted protocol. This holds especially true for legacy applications.

It’s also popular to use it for connecting to a local network from the outside. For example, an employee using SSH tunnels to connect to a company’s intranet.

You may be thinking this sounds like a VPN. The two are similar, but creating ssh tunnels is for specific traffic, whereas VPNs are more for establishing general connections.

SSH port forwarding will allow you to access remote resources by just establishing an SSH tunnel. The only requirement is that you have SSH access to the remote system and, ideally, public key authentication configured for password-less SSHing.

How many sessions are possible?

Technically, you can specify as many port forwarding sessions as you’d like. Networks use 65,535 different ports, and you are able to forward any of them that you want.

When forwarding traffic, be cognizant of the services that use certain ports. For example, port 80 is reserved for HTTP. So you would only want to forward traffic on port 80 if you intend to forward web requests.

The port you forward on your local system doesn’t have to match that of the remote server. For example, you can forward port 8080 on localhost to port 80 on the remote host.

If you don’t care what port you are using on the local system, select one between 2,000 and 10,000 since these are rarely used ports. Smaller numbers are typically reserved for certain protocols.

Local forwarding

Local forwarding involves forwarding a port from the client system to a server. It allows you to configure a port on your system so that all connections to that port will get forwarded through the SSH tunnel.

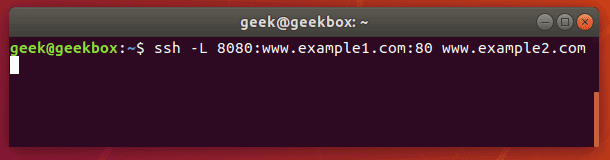
Use the -L switch in your ssh command to specify local port forwarding. The general syntax of the command is like this:

ssh -L local_port:remote_ip:remote_port [email protected]

Check out the example below:

ssh -L 80:example1.com:80 example2.com

local port forwarding

This command would forward all requests to example1.com to example2.com. Any user on this system that opens a web browser and attempts to navigate to example1.com will, in the background, have their request sent to example2.com instead and display a different website.

Such a command is useful when configuring external access to a company intranet or other private network resources.

Test SSH port forwarding

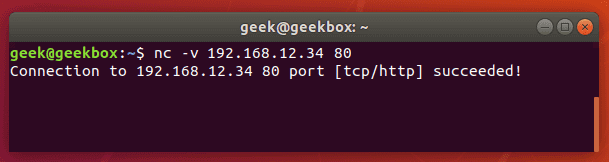
To see if your port forwarding is working correctly, you can use the netcat command. On the client machine (the system where you ran the ssh -L command), type the netcat command with this syntax:

nc -v remote_ip port_number

Test port forwarding using netcat

If the port is forwarded and data is able to traverse the connection successfully, netcat will return with a success message. If it doesn’t work, the connection will time out.

If you’re having trouble getting the port forwarding to work, make sure you’re able to ssh into the remote server normally and that you have configured the ports correctly. Also, verify that the connection isn’t being blocked by a firewall.

Persistent SSH tunnels (Using Autossh)

Autossh is a tool that can be used to create persistent SSH tunnels. The only prerequisite is that you need to have public key authentication configured between your systems, unless you want to be prompted for a password every time the connection dies and is reestablished.

Autossh may not be installed by default on your system, but you can quickly install it using apt, yum, or whatever package manager your distribution uses.

sudo apt-get install autossh

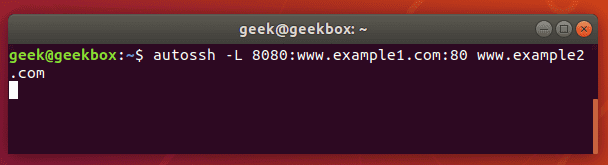
The autossh command is going to look pretty much identical to the ssh command we ran earlier.

autossh -L 80:example1.com:80 example2.com

Persistent SSH port forwarding autossh

Autossh will make sure that tunnels are automatically re-established in case they close because of inactivity, remote machine rebooting, network connection being lost, etc.

Remote forwarding

Remote port forwarding is used to give a remote machine access to your system. For example, if you want a service on your local computer to be accessible by a system(s) on your company’s private network, you could configure remote port forwarding to accomplish that.

To set this up, issue an ssh command with the following syntax:

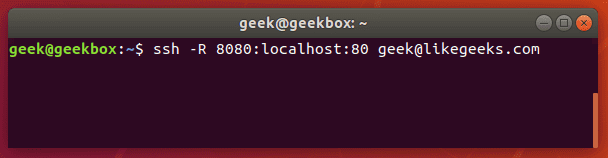
ssh -R remote_port:local_ip:local_port [email protected]

If you have a local web server on your computer and would like to grant access to it from a remote network, you could forward port 8080 (common http alternative port) on the remote system to port 80 (http port) on your local system.

ssh -R 8080:localhost:80 [email protected]

Remote port forwarding

Dynamic forwarding

SSH dynamic port forwarding will make SSH act as a SOCKS proxy server. Rather than forwarding traffic on a specific port (the way local and remote port forwarding do), this will forward traffic across a range of ports.

If you have ever used a proxy server to visit a blocked website or view location-restricted content (like viewing stuff on Netflix that isn’t available in your country), you probably used a SOCKS server.

It also provides privacy, since you can route your traffic through a SOCKS server with dynamic port forwarding and prevent anyone from snooping log files to see your network traffic (websites visited, etc).

To set up dynamic port forwarding, use the ssh command with the following syntax:

ssh -D local_port [email protected]

So, if we wanted to forward traffic on port 1234 to our SSH server:

ssh -D 1234 [email protected]

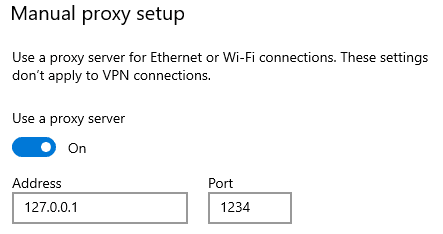
Once you’ve established this connection, you can configure applications to route traffic through it. For example, on your web browser:

Socks proxy

Type the loopback address (127.0.0.1) and the port you configured for dynamic port forwarding, and all traffic will be forwarded through the SSH tunnel to the remote host (in our example, the likegeeks.com SSH server).

Multiple forwarding

For local port forwarding, if you’d like to setup more than one port to be forwarded to a remote host, you just need to specify each rule with a new -L switch each time. The command syntax is like this:

ssh -L local_port_1:remote_ip:remote_port_1 -L local_port_2:remote_ip:remote_port2 [email protected]

For example, if you want to forward ports 8080 and 4430 to 192.168.1.1 ports 80 and 443 (HTTP and HTTPS), respectively, you would use this command:

ssh -L 8080:192.168.1.1:80 -L 4430:192.168.1.1:443 [email protected]

For remote port forwarding, you can setup more than one port to be forwarded by specifying each new rule with the -R switch. The command syntax is like this:

ssh -R remote_port1:local_ip:local_port1 remote_port2:local_ip:local_port2 [email protected]

List port forwarding

You can see what SSH tunnels are currently established with the lsof command.

lsof -i | egrep '\<ssh\>'

SSH tunnels

In this screenshot, you can see that there are 3 SSH tunnels established. Add the -n flag to have IP addresses listed instead of resolving the hostnames.

lsof -i -n | egrep '\<ssh\>'

SSH tunnels n flag

Limit forwarding

By default, SSH port forwarding is pretty open. You can freely create local, remote, and dynamic port forwards as you please.

But if you don’t trust some of the SSH users on your system, or you’d just like to enhance security in general, you can put some limitations on SSH port forwarding.

There are a couple of different settings you can configure inside the sshd_config file to put limitations on port forwarding. To configure this file, edit it with vi, nano, or your favorite text editor:

sudo vi /etc/ssh/sshd_config

PermitOpen can be used to specify the destinations to which port forwarding is allowed. If you only want to allow forwarding to certain IP addresses or hostnames, use this directive. The syntax is as follows:

PermitOpen host:port

PermitOpen IPv4_addr:port

PermitOpen [IPv6_addr]:port

AllowTCPForwarding can be used to turn SSH port forwarding on or off, or specify what type of SSH port forwarding is permitted. Possible configurations are:

AllowTCPForwarding yes #default setting

AllowTCPForwarding no #prevent all SSH port forwarding

AllowTCPForwarding local #allow only local SSH port forwarding

AllowTCPForwarding remote #allow only remote SSH port forwarding

To see more information about these options, you can check out the man page:

man sshd_config

Low latency

The only real problem that arises with SSH port forwarding is that there is usually a bit of latency. You probably won’t notice this as an issue if you’re doing something minor, like accessing text files or small databases.

The problem becomes more apparent when doing network intensive activities, especially if you have port forwarding set up as a SOCKS proxy server.

The reason for the latency is because SSH is tunneling TCP over TCP. This is a terribly inefficient way to transfer data and will result in slower network speeds.

You could use a VPN to prevent the issue, but if you are determined to stick with SSH tunnels, there is a program called sshuttle that corrects the issue. Ubuntu and Debian-based distributions can install it with apt-get:

sudo apt-get install sshuttle

If you package manager on your distribution doesn’t have sshuttle in its repository, you can clone it from GitHub:

git clone https://github.com/sshuttle/sshuttle.git

cd sshuttle

./setup.py install

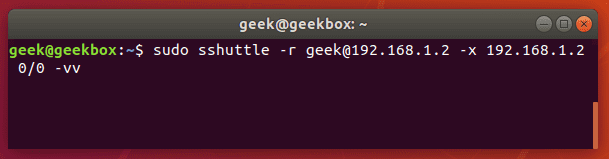
Setting up a tunnel with sshuttle is different from the normal ssh command. To setup a tunnel that forwards all traffic (akin to a VPN):

sudo sshuttle -r user@remote_ip -x remote_ip 0/0 -vv

sshuttle command

Break the connection with a ctrl+c key combination in the terminal. Alternatively, to run the sshuttle command as a daemon, add the -D switch to your command.

Want to make sure that the connection was established and the internet sees you at the new IP address? You can run this curl command:

curl ipinfo.io

curl IP address

I hope you find the tutorial useful. Keep coming back.

0

15+ examples for Linux cURL command

In this tutorial, we will cover the cURL command in Linux. Follow along as we guide you through the functions of this powerful utility with examples to help you understand everything it’s capable of. The cURL command is used to download or upload data to a server, using one of its 20+ supported protocols. This data could be a file, email message, or web page. What is cURL command? cURL is an ideal tool for interacting with a website or API, sending requests and displaying the responses to the terminal or logging the data to a file. Sometimes it’s used as part of a larger script, handing off the retrieved data to other functions for processing. Since cURL can be used to retrieve files from servers, it’s often used to download part of a website. It performs this function well, but sometimes the wget command is better suited for that job. We’ll go over some of the differences and similarities between wget and cURL later in this article. We’ll show you how to get started using cURL in the sections below.

Continue Reading →

Download a file

The most basic command we can give to cURL is to download a website or file. cURL will use HTTP as its default protocol unless we specify a different one. To download a website, just issue this command:

curl http://www.google.com

Of course, enter any website or page that you want to retrieve.
curl basic command

Doing a basic command like this with no extra options will rarely be useful, because this only tells cURL to retrieve the source code of the page you’ve provided.
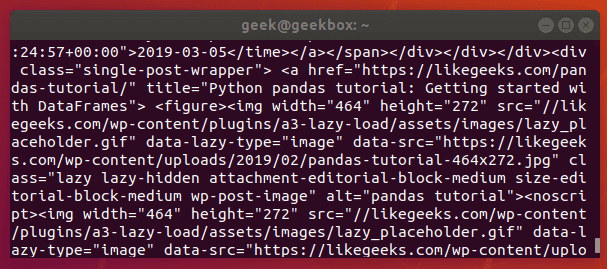
curl output

When we ran our command, our terminal is filled with HTML and other web scripting code – not something that is particularly useful to us in this form.

Let’s download the website as an HTML document instead, that way the content can be displayed. Add the –output option to cURL to achieve this.
curl output switch

Now the website we downloaded can be opened and displayed in a web browser.
downloaded website

If you’d like to download an online file, the command is about the same. But make sure to append the –output option to cURL as we did in the example above.

If you fail to do so, cURL will send the binary output of the online file to your terminal, which will likely cause it to malfunction.

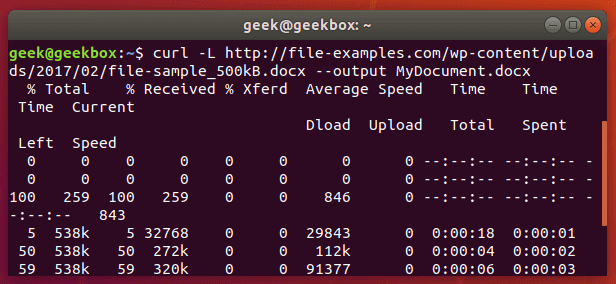
Here’s what it looks like when we initiate the download of a 500KB word document.
curl download document

The word document begins to download and the current progress of the download is shown in the terminal. When the download completes, the file will be available in the directory we saved it to.

In this example, no directory was specified, so it was saved to our present working directory (the directory from which we ran the cURL command).

Also, did you notice the -L option that we specified in our cURL command? It was necessary in order to download this file, and we go over its function in the next section.

Follow redirect

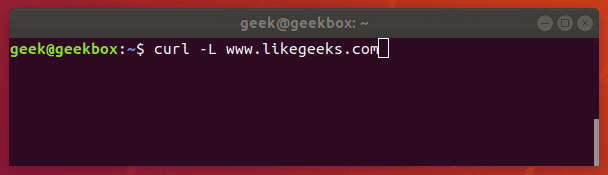
If you get an empty output when trying to cURL a website, it probably means that the website told cURL to redirect to a different URL. By default, cURL won’t follow the redirect, but you can tell it to with the -L switch.

curl -L www.likegeeks.com
curl follow redirect

In our research for this article, we found it was necessary to specify the -L on a majority of websites, so be sure to remember this little trick. You may even want to append it to the majority of your cURL commands by default.

Stop and resume download

If your download gets interrupted, or if you need to download a big file but don’t want to do it all in one session, cURL provides an option to stop and resume the transfer.

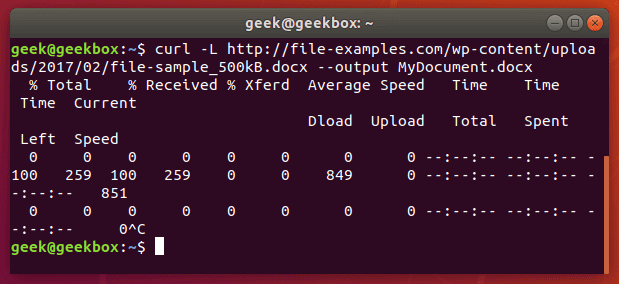
To stop a transfer manually, you can just end the cURL process the same way you’d stop almost any process currently running in your terminal, with a ctrl+c combination.
curl stop download

Our download has begun, but was interrupted with ctrl+c, now let’s resume it with the following syntax:

curl -C - example.com/some-file.zip --output MyFile.zip

The -C switch is what resumes our file transfer, but also notice that there is a dash (-) directly after it. This tells cURL to resume the file transfer, but to first look at the already downloaded portion in order to see the last byte downloaded and determine where to resume.
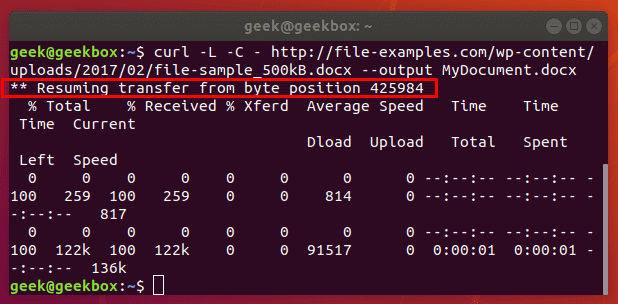
resume file download

Our file transfer was resumed and then proceeded to finish downloading successfully.

Specify timeout

If you want cURL to abandon what it’s doing after a certain amount of time, you can specify a timeout in the command. This is especially useful because some operations in cURL don’t have a timeout by default, so one needs to be specified if you don’t want it getting hung up indefinitely.

You can specify a maximum time to spend executing a command with the -m switch. When the specified time has elapsed, cURL will exit whatever it’s doing, even if it’s in the middle of downloading or uploading a file.

cURL expects your maximum time to be specified in seconds. So, to timeout after one minute, the command would look like this:

curl -m 60 example.com

Another type of timeout that you can specify with cURL is the amount of time to spend connecting. This helps make sure that cURL doesn’t spend an unreasonable amount of time attempting to contact a host that is offline or otherwise unreachable.

It, too, accepts seconds as an argument. The option is written as –connect-timeout.

curl --connect-timeout 60 example.com

Using a username and a password

You can specify a username and password in a cURL command with the -u switch. For example, if you wanted to authenticate with an FTP server, the syntax would look like this:

curl -u username:password ftp://example.com
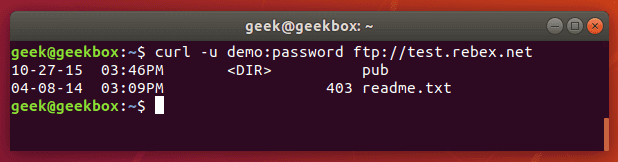
curl authenticate

You can use this with any protocol, but FTP is frequently used for simple file transfers like this.

If we wanted to download the file displayed in the screenshot above, we just issue the same command but use the full path to the file.

curl -u username:password ftp://example.com/readme.txt
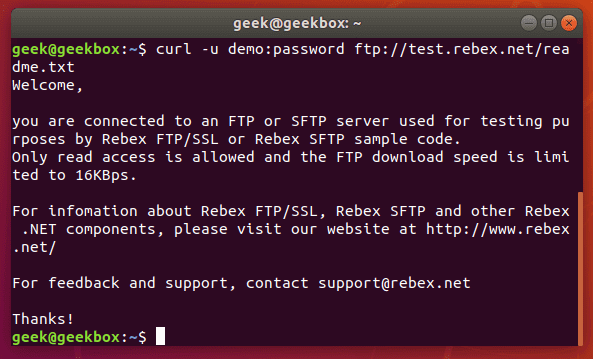
curl authenticate download

Use proxies

It’s easy to direct cURL to use a proxy before connecting to a host. cURL will expect an HTTP proxy by default, unless you specify otherwise.

Use the -x switch to define a proxy. Since no protocol is specified in this example, cURL will assume it’s an HTTP proxy.

curl -x 192.168.1.1:8080 http://example.com

This command would use 192.168.1.1 on port 8080 as a proxy to connect to example.com.

You can use it with other protocols as well. Here’s an example of what it’d look like to use an HTTP proxy to cURL to an FTP server and retrieve a file.

curl -x 192.168.1.1:8080 ftp://example.com/readme.txt

cURL supports many other types of proxies and options to use with those proxies, but expanding further would be beyond the scope of this guide. Check out the cURL man page for more information about proxy tunneling, SOCKS proxies, authentication, etc.

Chunked download large files

We’ve already shown how you can stop and resume file transfers, but what if we wanted cURL to only download a chunk of a file? That way, we could download a large file in multiple chunks.

It’s possible to download only certain portions of a file, in case you needed to stay under a download cap or something like that. The –range flag is used to accomplish this.
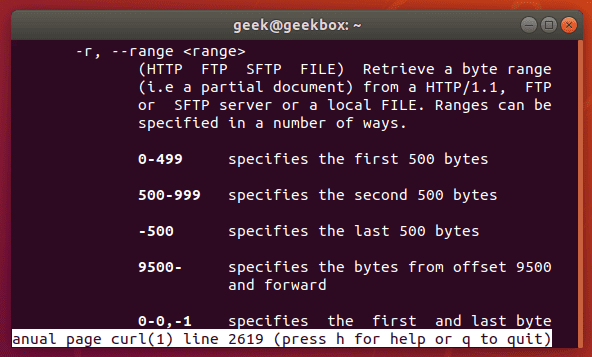
curl range man

Sizes must be written in bytes. So if we wanted to download the latest Ubuntu .iso file in 100 MB chunks, our first command would look like this:

curl --range 0-99999999 http://releases.ubuntu.com/18.04/ubuntu-18.04.3-desktop-amd64.iso ubuntu-part1

The second command would need to pick up at the next byte and download another 100 MB chunk.

curl --range 0-99999999 http://releases.ubuntu.com/18.04/ubuntu-18.04.3-desktop-amd64.iso ubuntu-part1

curl --range 100000000-199999999 http://releases.ubuntu.com/18.04/ubuntu-18.04.3-desktop-amd64.iso ubuntu-part2

Repeat this process until all the chunks are downloaded. The last step is to combine the chunks into a single file, which can be done with the cat command.

cat ubuntu-part? > ubuntu-18.04.3-desktop-amd64.iso

Client certificate

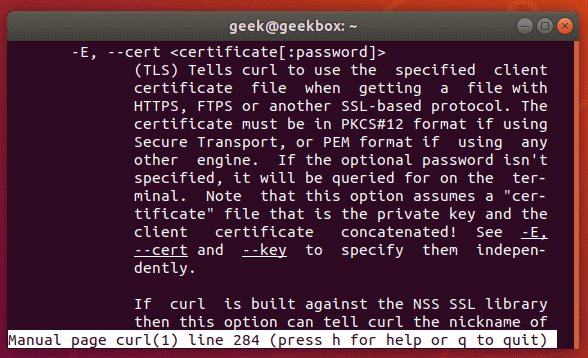
To access a server using certificate authentication instead of basic authentication, you can specify a certificate file with the –cert option.

curl --cert path/to/cert.crt:password ftp://example.com

cURL has a lot of options for the format of certificate files.
curl cert

There are more certificate related options, too: –cacert, –cert-status, –cert-type, etc. Check out the man page for a full list of options.

Silent cURL

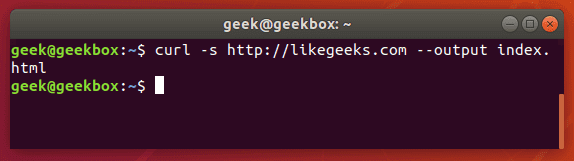
If you’d like to suppress cURL’s progress meter and error messages, the -s switch provides that feature. It will still output the data you request, so if you’d like the command to be 100% silent, you’d need to direct the output to a file.

Combine this command with the -O flag to save the file in your present working directory. This will ensure that cURL returns with 0 output.

curl -s -O http://example.com

Alternatively, you could use the –output option to choose where to save the file and specify a name.

curl -s http://example.com --output index.html
curl silent

Get headers

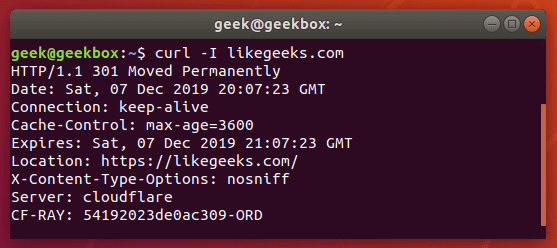
Grabbing the header of a remote address is very simple with cURL, you just need to use the -I option.

curl -I example.com
curl headers

If you combine this with the –L option, cURL will return the headers of every address that it’s redirected to.

curl -I -L example.com

Multiple headers

You can pass headers to cURL with the -H option. And to pass multiple headers, you just need to use the -H option multiple times. Here’s an example:

curl -H 'Connection: keep-alive' -H 'Accept-Charset: utf-8 ' http://example.com

Post (upload) file

POST is a common way for websites to accept data. For example, when you fill out a form online, there’s a good chance that the data is being sent from your browser using the POST method. To send data to a website in this way, use the -d option.

curl -d 'name=geek&location=usa' http://example.com

To upload a file, rather than text, the syntax would look like this:

curl -d @filename http://example.com

Use as many -d flags as you need in order to specify all the different data or filenames that you are trying to upload.

You can the -T option if you want to upload a file to an FTP server.

curl -T myfile.txt ftp://example.com/some/directory/

Send an email

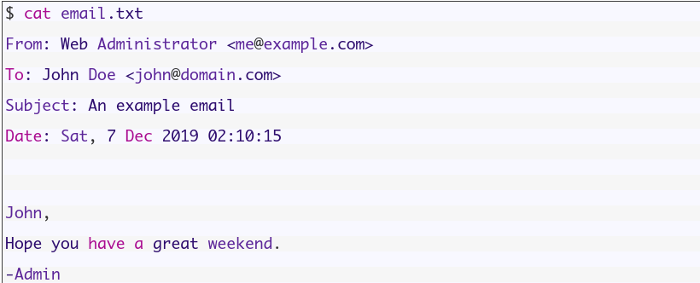
Sending an email is simply uploading data from your computer (or another device) to an email server. Since cURL is able to upload data, we can use it to send emails. There are a slew of options, but here’s an example of how to send an email through an SMTP server:

curl smtp://mail.example.com --mail-from [email protected] --mail-rcpt [email protected] --upload-file email.txt

Your email file would need to be formatted correctly. Something like this:
As usual, more granular and specialized options can be found in the man page of cURL.

Read email message

cURL supports IMAP (and IMAPS) and POP3, both of which can be used to retrieve email messages from a mail server.

Login using IMAP like this:

curl -u username:password imap://mail.example.com

This command will list available mailboxes, but not view any specific message. To do this, specify the UID of the message with the –X option.

curl -u username:password imap://mail.example.com -X 'UID FETCH 1234'

Difference between cURL and wget

Sometimes people confuse cURL and wget because they’re both capable of retrieving data from a server. But this is the only thing they have in common.

We’ve shown in this article what cURL is capable of. wget provides a different set of functions. wget is the best tool for downloading websites and is capable of recursively traversing directories and links to download entire sites.

For downloading websites, use wget. If using some protocol other than HTTP or HTTPS, or for uploading files, use cURL. cURL is also a good option for downloading individual files from the web, although wget does that fine, too.

I hope you find the tutorial useful. Keep coming back.
0